Blog

A Practical Guide on How to Scrape the Web with Python /  by Usamah Khan

I often catch myself asking questions of the world. Sometimes those questions have easy answers that I can get by talking to a friend or asking a colleague. Other times, the answers are a little harder to come by but can come from a quick Google search or reading an article or book on the subject. However, every now and again, you ask a question that doesn’t seem like anyone’s asked before. This is when you need to dig deep, research, go through the data and figure out the answer.

This used to be the point at which I would hit a wall - when trying to find data-driven answers to questions. Most of the time, the data is out there, it’s just in a format that’s better suited for human readability, not machine readability. That’s when you need to need to pull up your sleeves, grab a coffee and copy-paste the data row-by-row, page-by-page. But that starts being problematic when you hit 257 pages of data with 100 rows on each page.

Enter the magic of the scraper.

I’ve done a few data projects, and in getting comfortable with scraping I’ve realized that it can be quite straightforward, provided you know a few things. The point of this guide is to be an easy first step to help anyone looking to scrape some data for their own projects. So let’s get started!

What You’ll Need To Know

While there are many programming languages out there that you could use, just due to my own comfort and experience, this post will guide you through scraping with Python. If you’re here and are familiar with Python, great! If not, here’re some great resources to get you up and running and learning with Python. For beginners though, I personally recommend using Anaconda - it makes managing packages and environments super easy.

Secondly, while I’ll go over the basics that you’ll need for this, it would be helpful to understand a little HTML as you need to understand how to navigate the source code of a page and find where the elements of interest are. This is a great free guide to HTML and I would especially recommend if you’re not already comfortable with it, refreshing yourself with the section on tables.

Also, I would recommend using Chrome while you look into websites to scrape. All browsers have developer tools to inspect a page, so feel free to use whatever you’re most comfortable with, but if you want to follow along, I’m used to Chrome and I’ll be using the screenshots I take from there.

Lastly, as I go along I’ll insert code chunks. If you copy-paste them in the order they appear in they should compile properly, but make sure not to skip any chunks! The GitHub repo with Notebook can be found here.

Scraping a Website

Step 1 - Inspect the Web Page

The first challenge in web scraping is gauging how difficult a scrape is going to be. This is also arguably the longest step and one that’s easy to get stuck on. Websites are varied in style and architecture and while you can scrape basically any website, getting usable data is a different question. It’s then the variability that will determine how difficult it will be to extract data. So what you want to do first is head on over to the site you want to scrape and scope out the layout and structure. As a general rule of thumb, if the page in question has information in a table format, chances are you will be able to scrape the data relatively easily.

1.1 - Explore and Find the Data you Want to Scrape

For this example, I’m going to pull an example from my Oscars project. I wanted to get a list of Actors and Actresses who won the Academy Award for Best Actor/Actress so I went to Wikipedia to find a list.

Scrolling down the page, we can see the data is in an easy to read table format with headers for the “Year”, “Actor”, “Role(s)”, and name of “Film”.
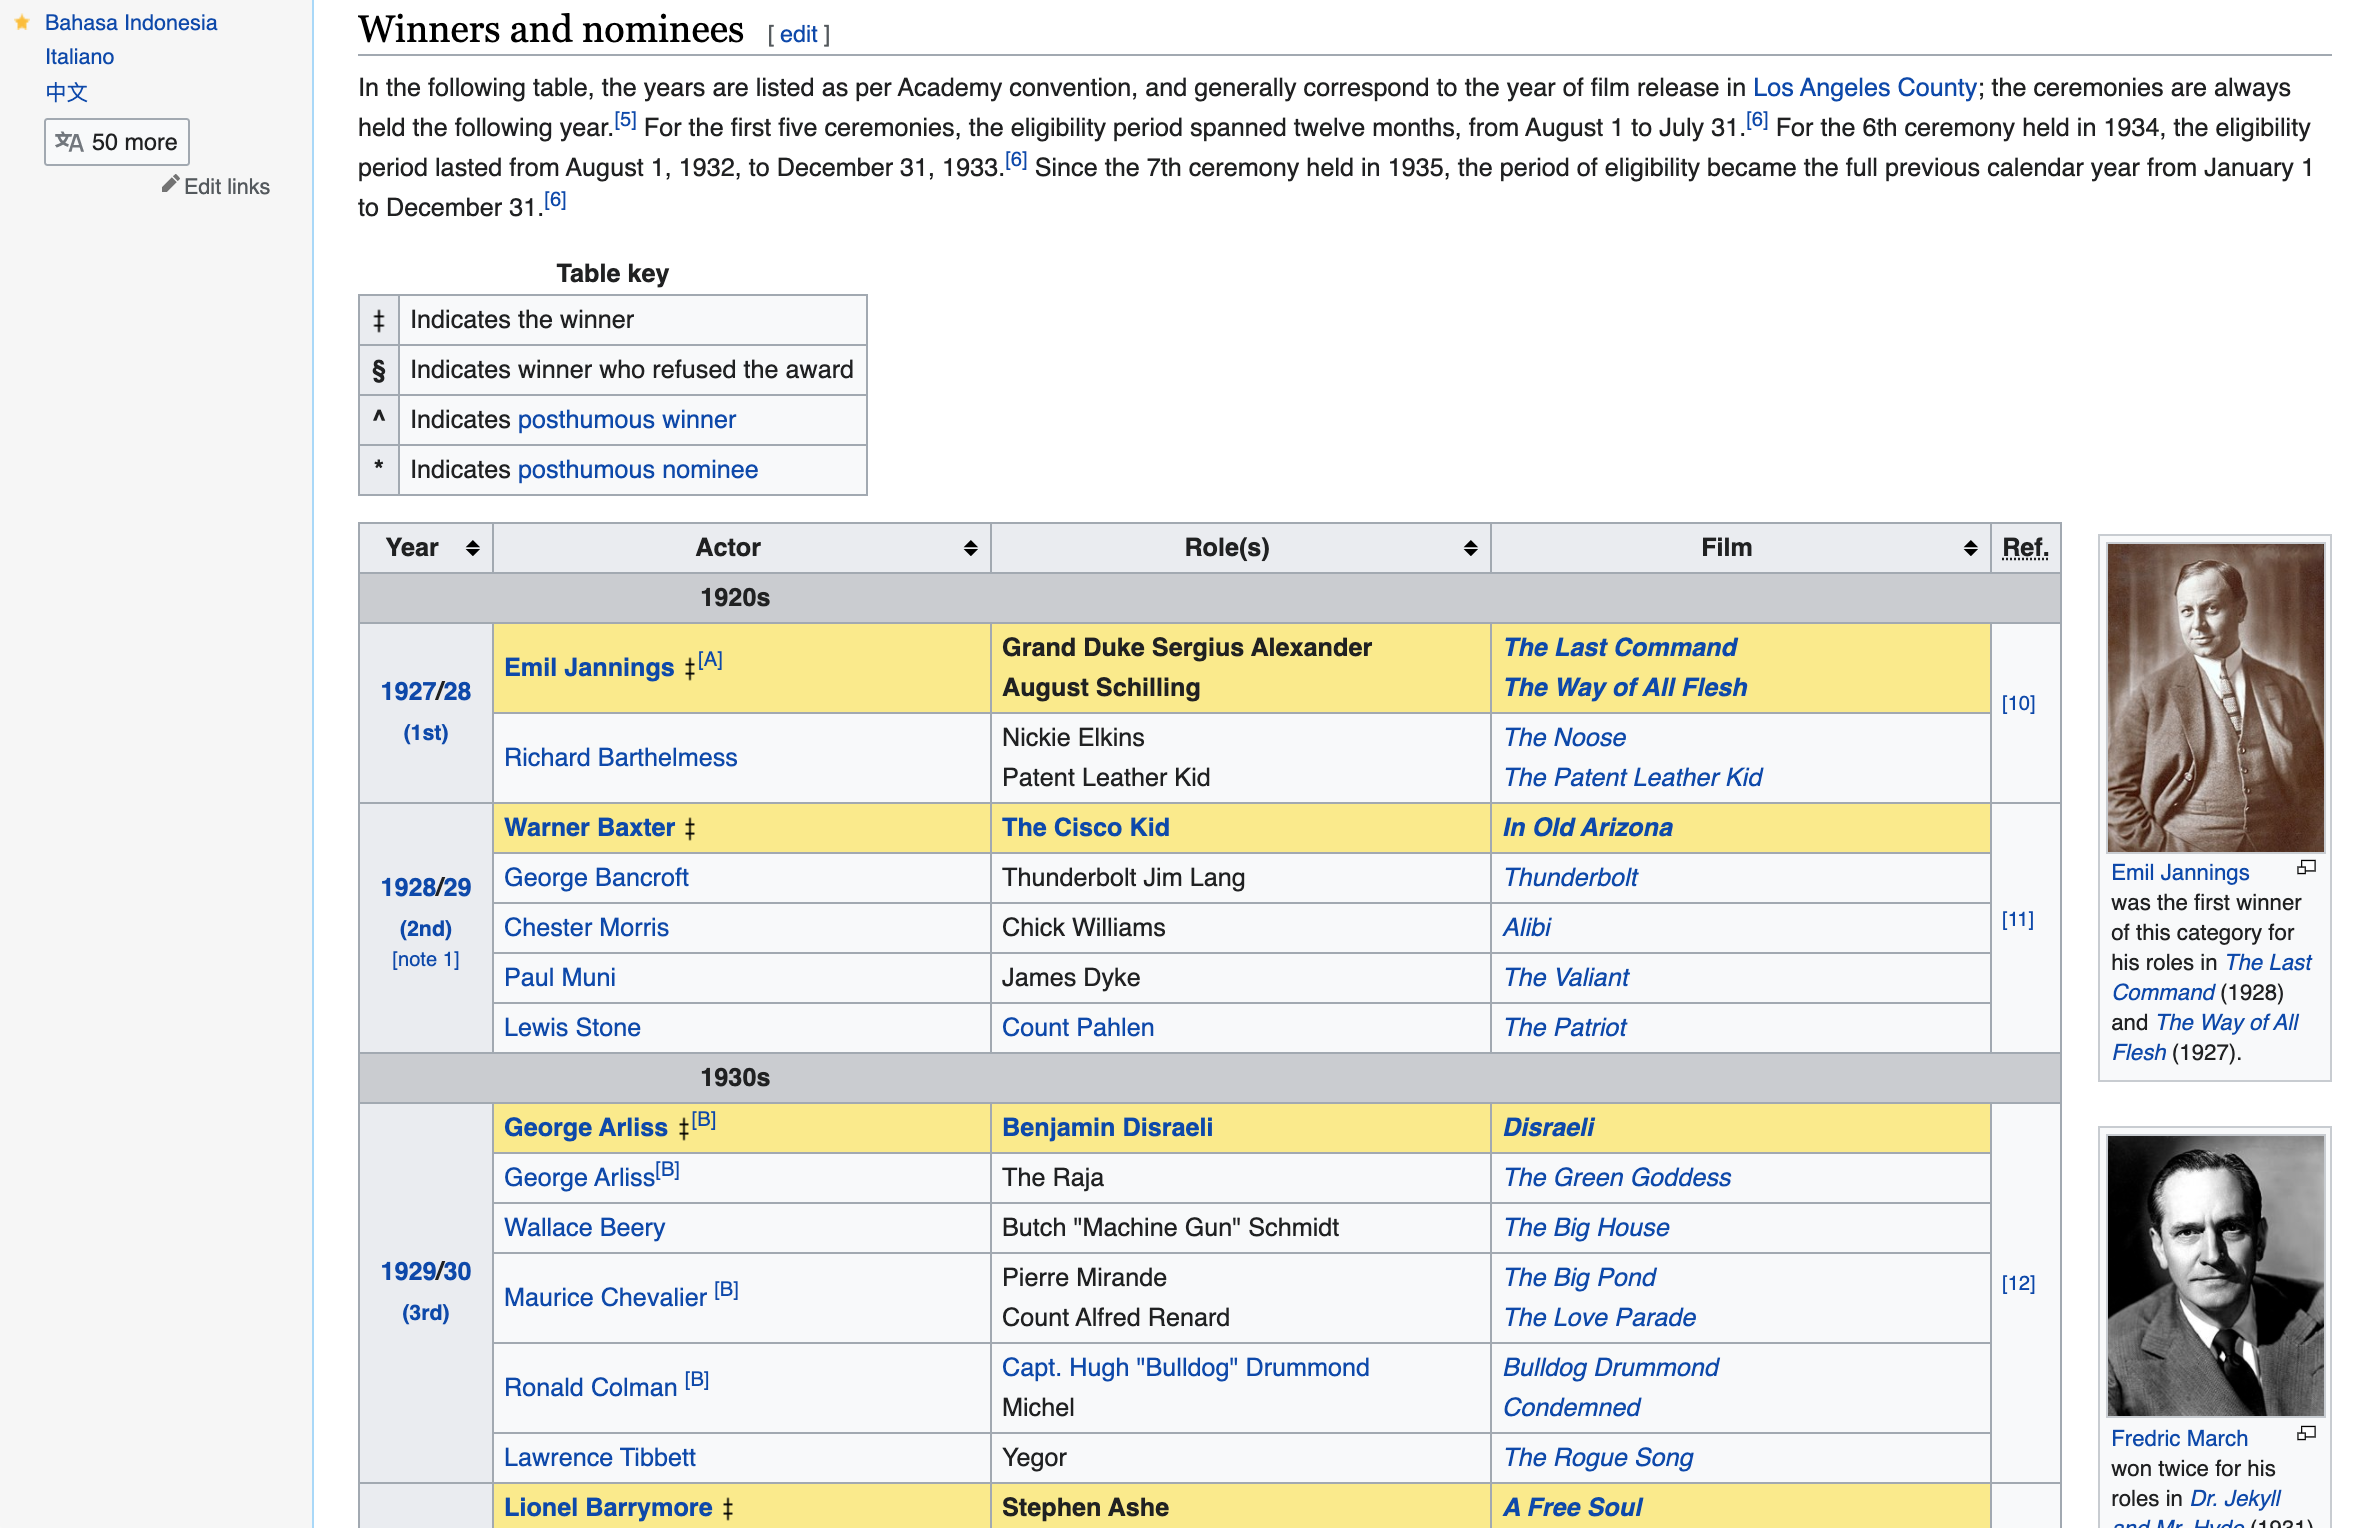
Screen grab of the Wikipedia Page for Best Actor

Screen grab of the Wikipedia Page for Best Actor

1.2 - Find where the data is located in the source code

Now that we know the data is in a table, the next step is to find out where exactly in the pages source code we can access the data. To find that out, we’re going to “Inspect” the page. To do so, right-click anywhere on the page, scroll down the menu and select “Inspect” as shown in the screenshot below.
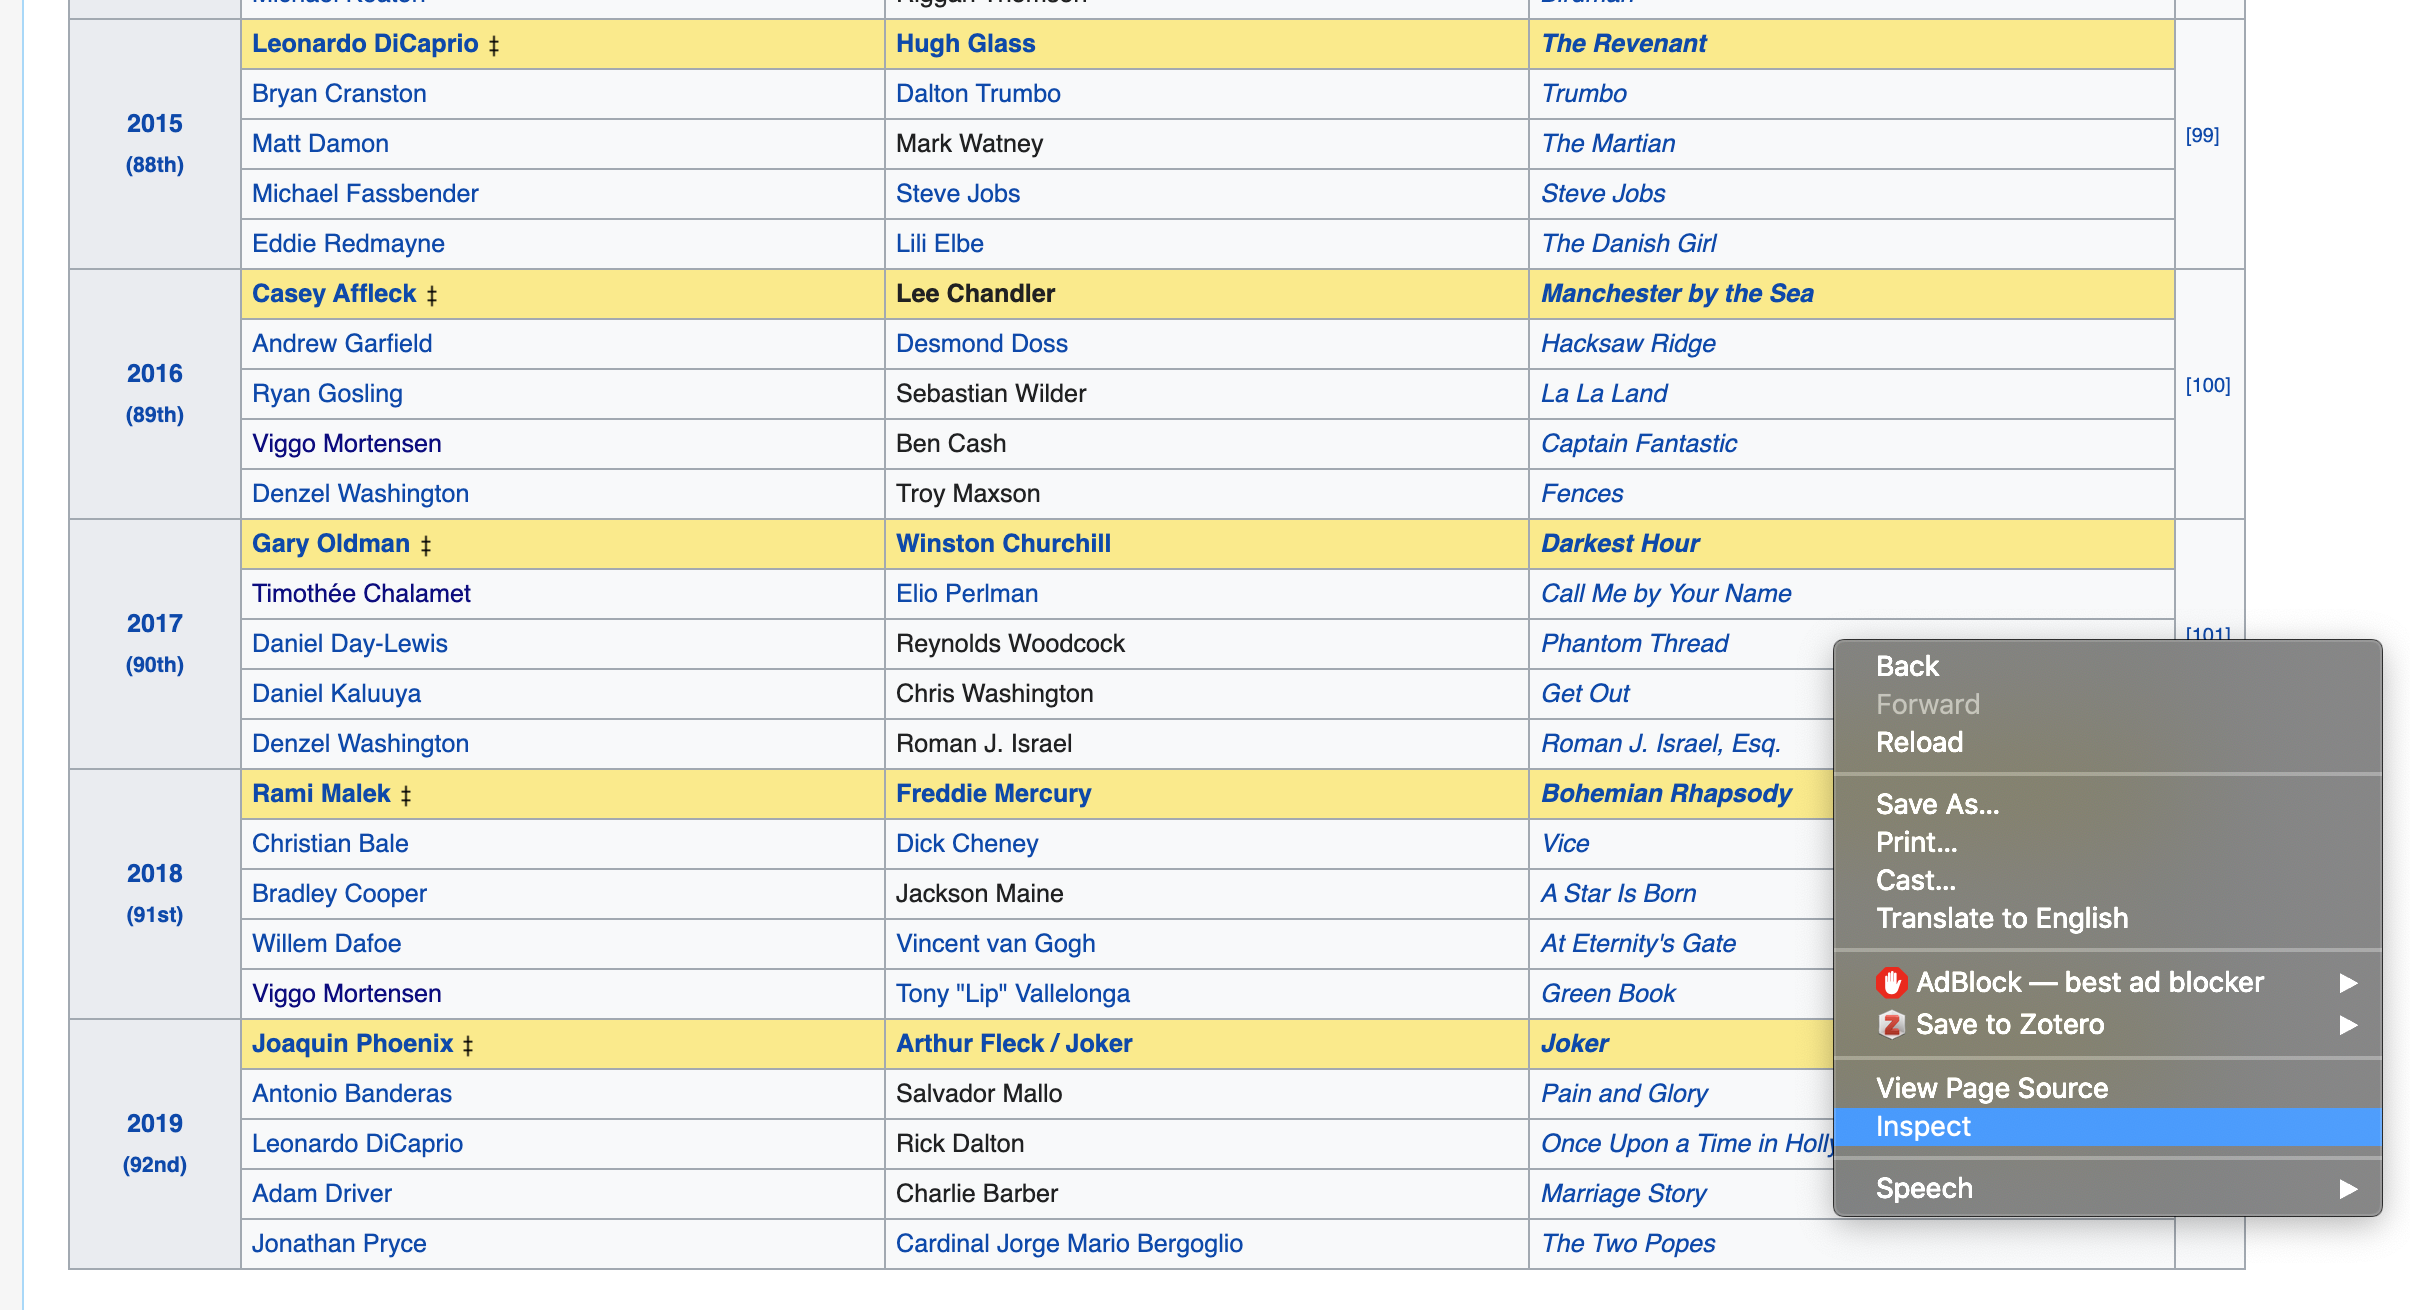
You should then see a console open up at the bottom of the screen. Here you can see the entire source code for the page, but more importantly, can inspect the different elements to get an exact idea of where in the code the item is. This is where knowledge of HTML will come in handy.


Recap of HTML Classes and IDs
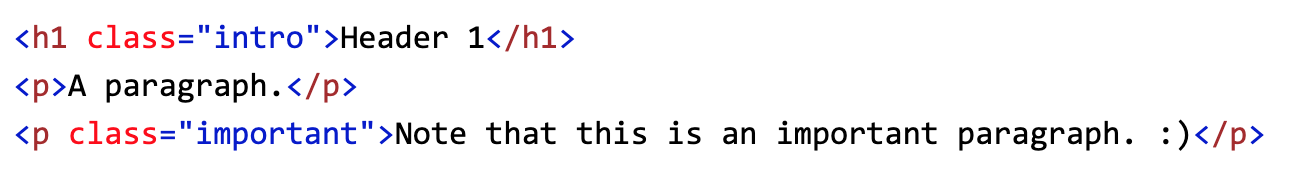
An example of a class take from w3schools - for more, follow the link here

An example of a class take from w3schools - for more, follow the link here

As a quick recap, in HTML, a name in the form of a class or an id can be attributed to any of the elements so that the stylesheet or JavaScript can point to it and make changes. Think about it like if someone wanted to access records at a workplace. Your id would be your name, while your class would be your department. Knowing this, an outsider could use either identification name to make departmental wide changes, or individual changes to the files. This is a simplified explanation and I highly advise looking into it more but for the purposes of this guide, it should suffice.


For us, we want to point the scraper to pull only the relevant information to us. So we want to know, under what identification or class, can we find the data. To find this, look at the console in your browser, and select the button highlighted below to inspect an element on the page.
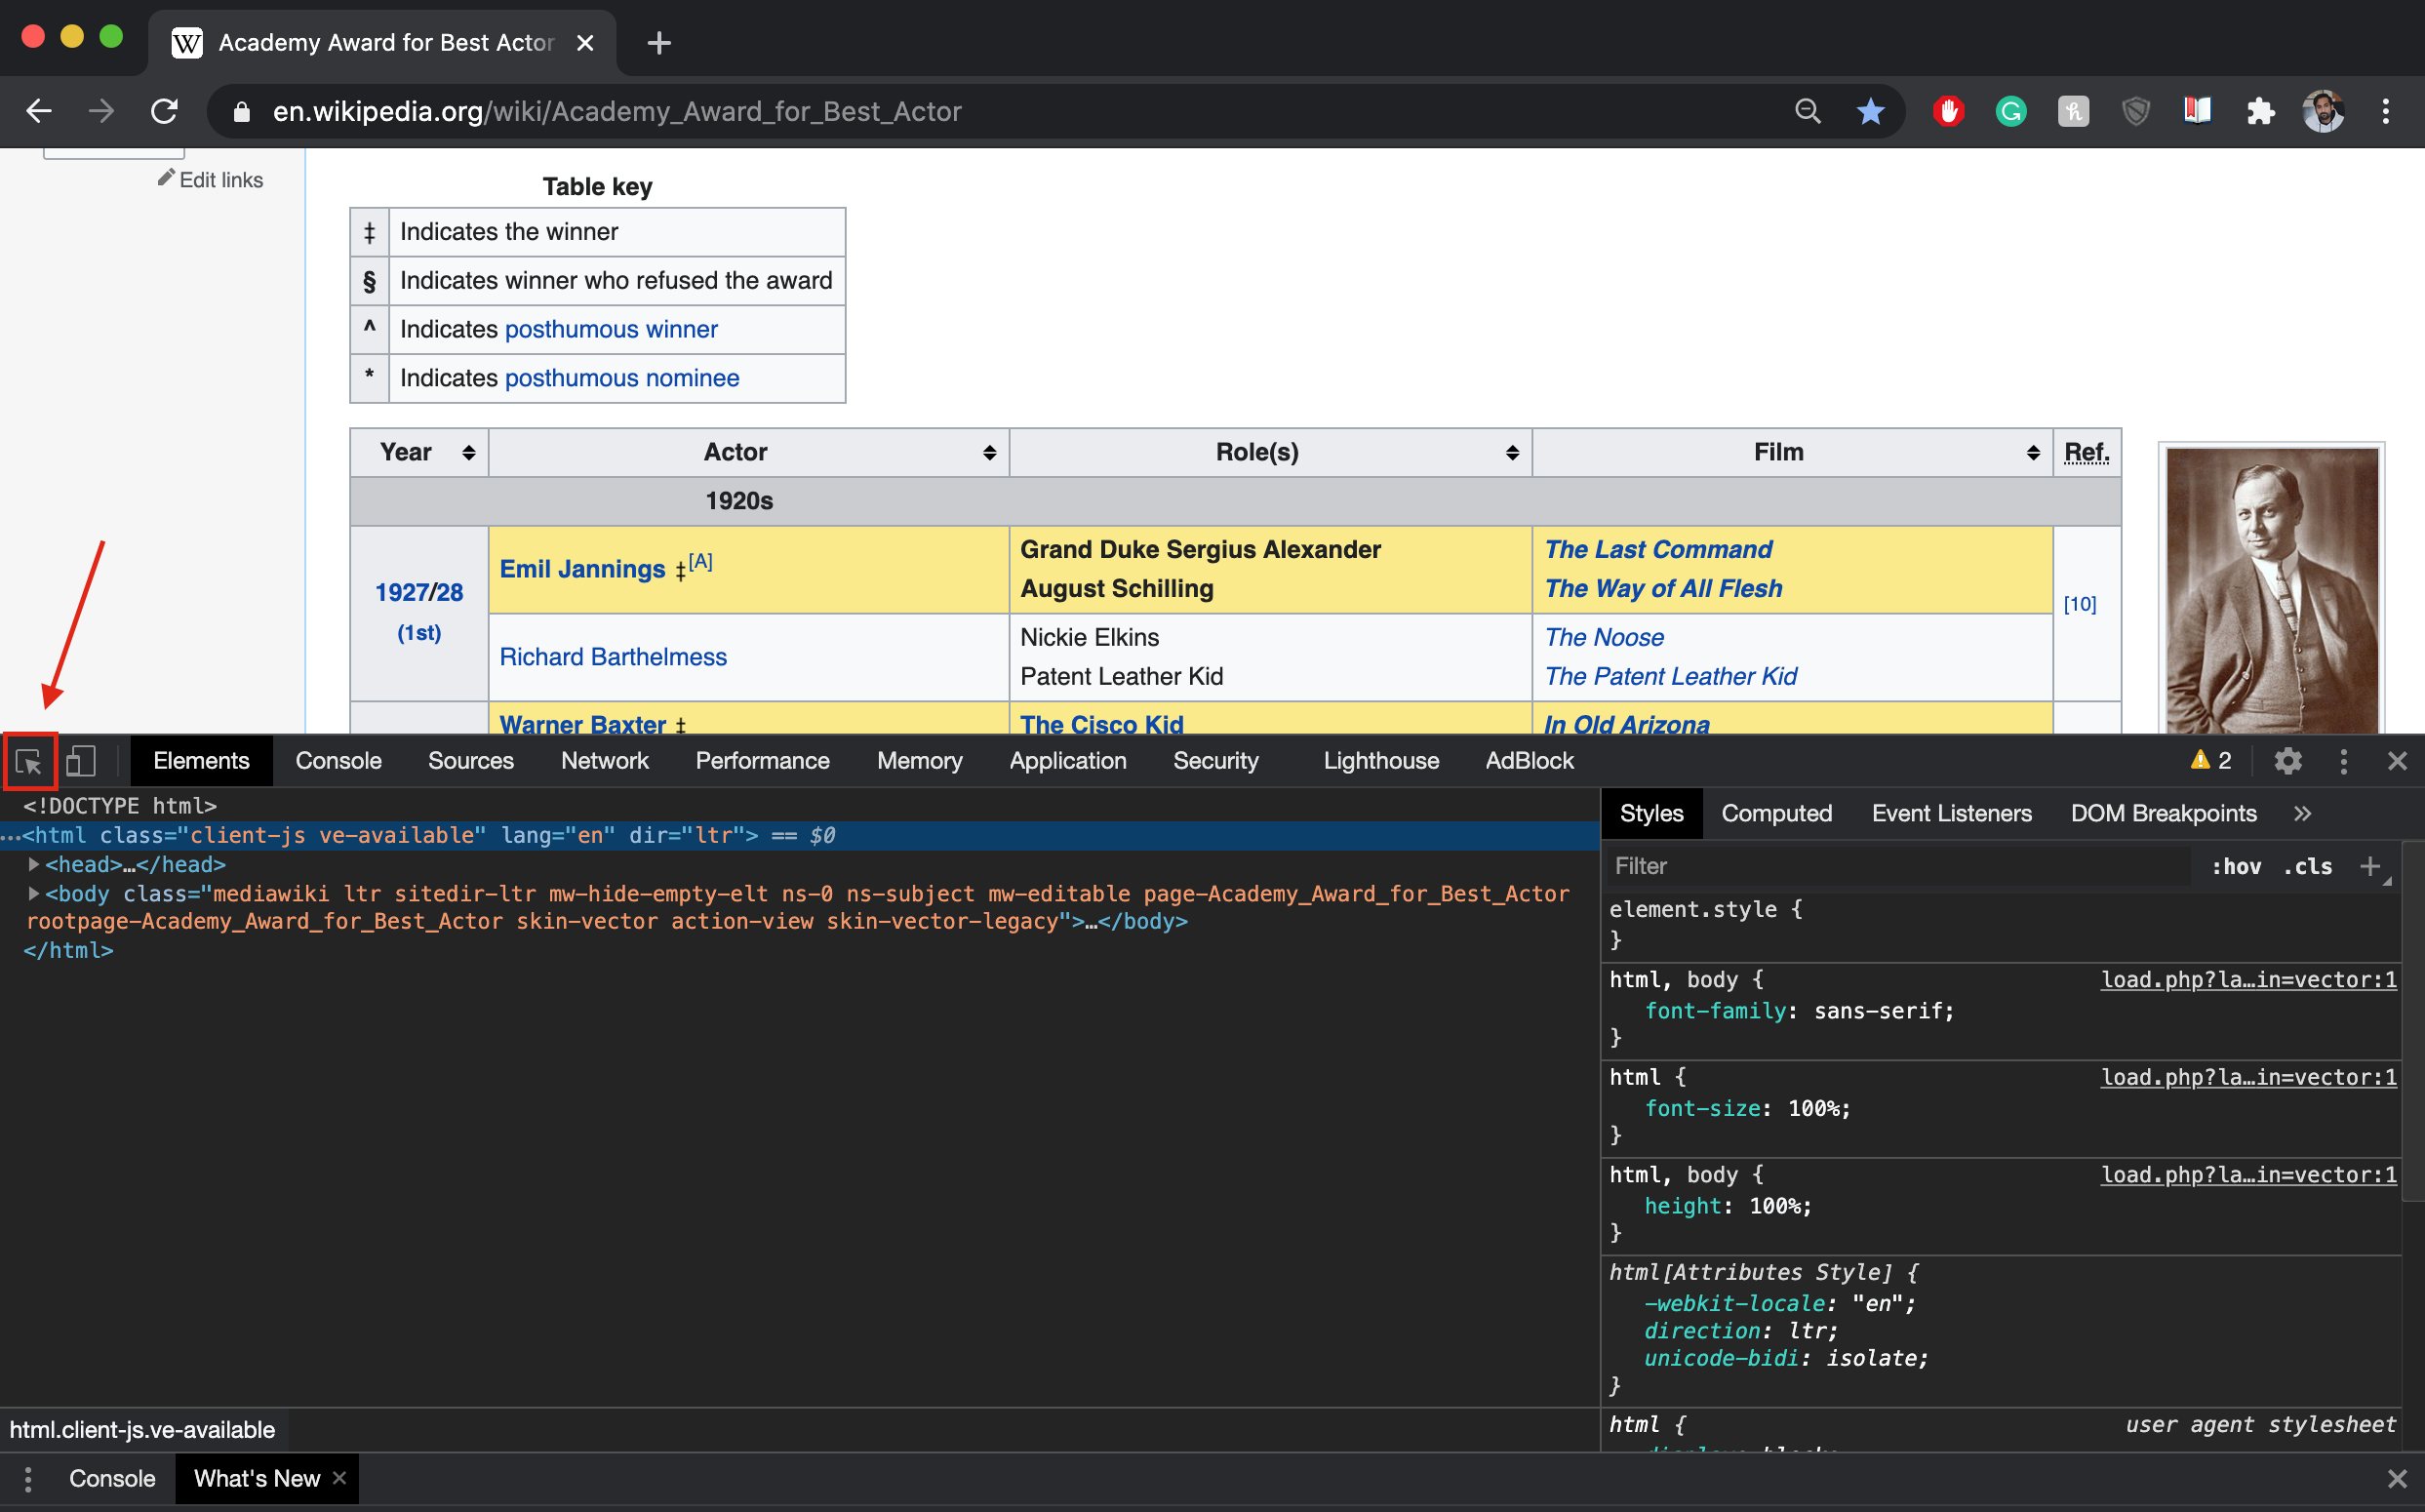
Screen Shot 2020-10-05 at 11.42.59 PM.png

Once in inspect mode select a data point in question that you’re looking to retrieve, in this case, the name of the actor.
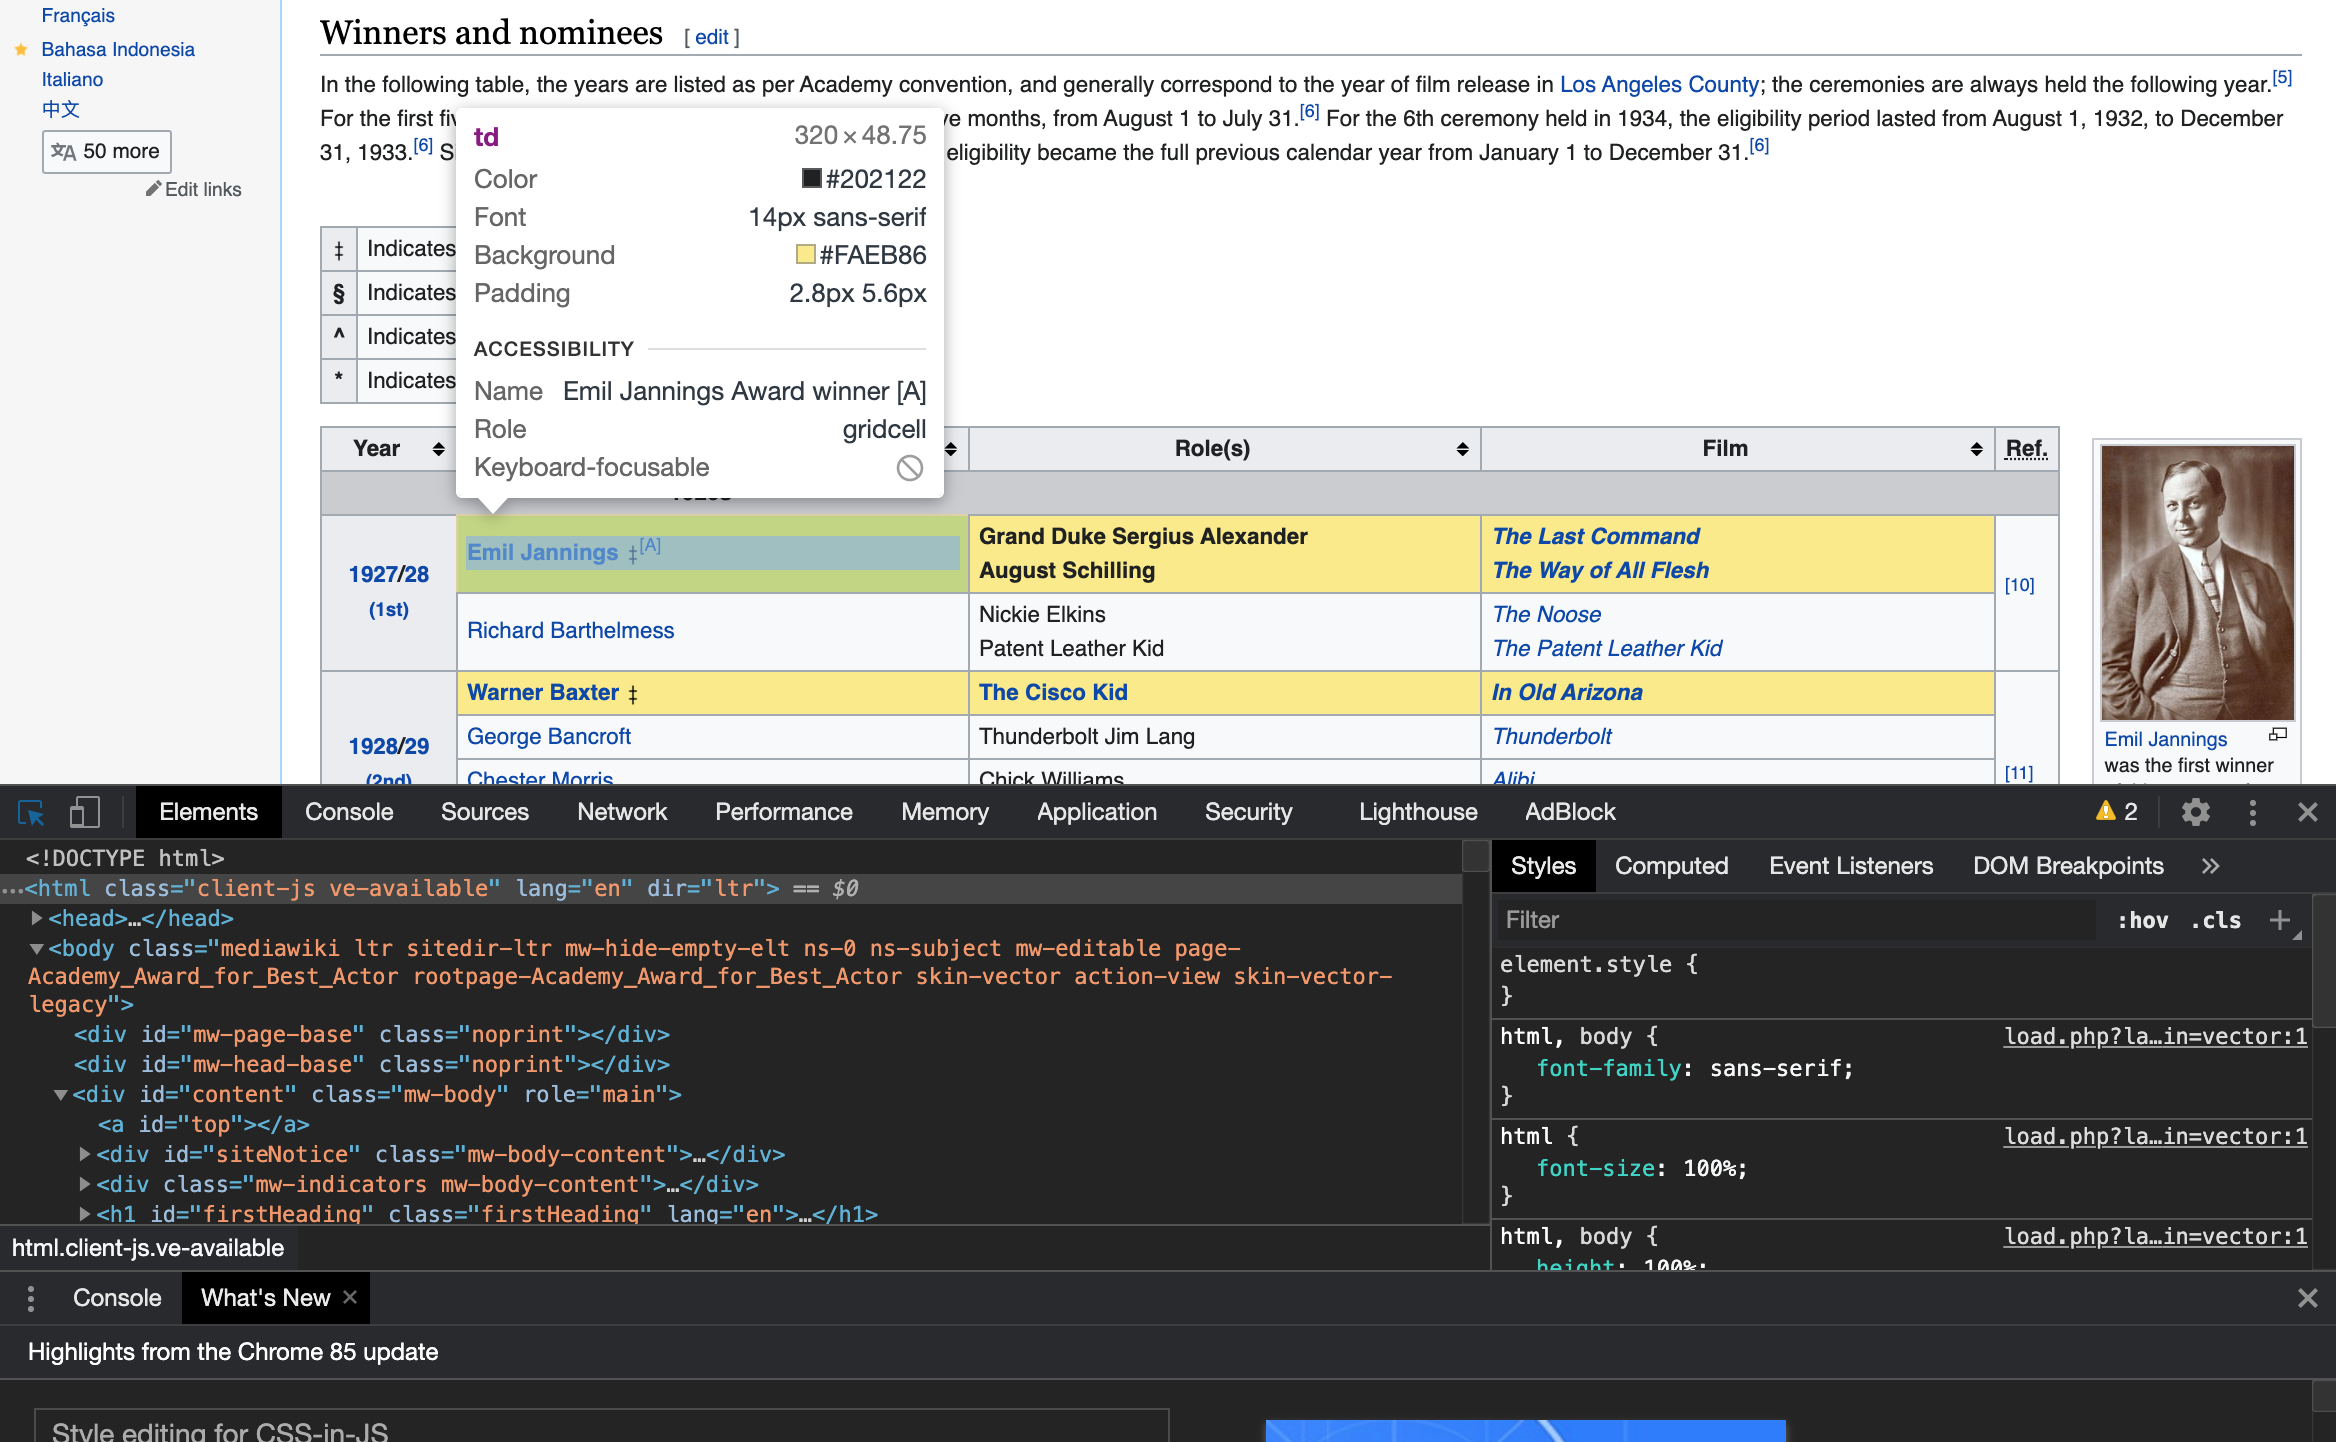
Once you’ve selected it with the inspect tool in the console you’ll see the exact location of the data in the table. In the screenshot below, I’ve broken down the items of importance.
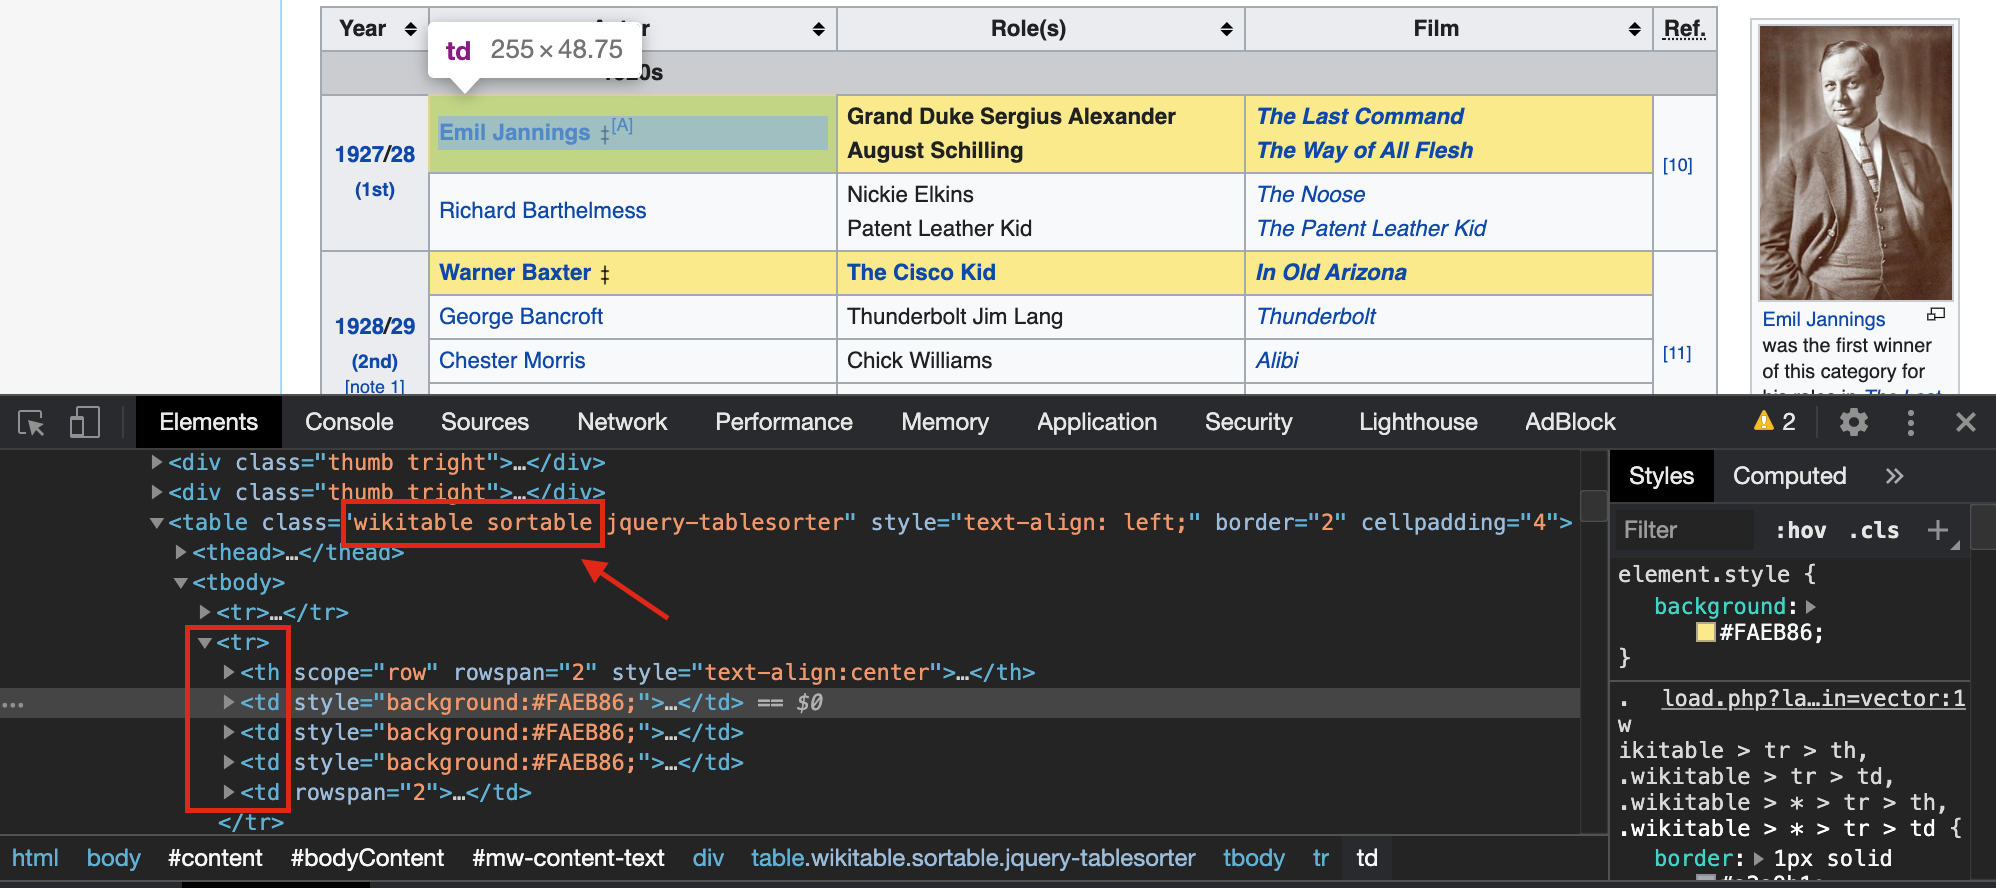
While there’s a lot of information here, I’ve highlighted whats important. In brief, we have 3 important things to take note of:

  1. The data is in a table with a class name of “wikitable sortable”

  2. The table rows can be accessed through the tr attribute

  3. The table data can be accessed through the td attribute

Quick tip you can also use this technique to inspect a font that you like and may want to use in a project.

We now have enough to go on to start with our scrape. I’d recommend spending some time with your browser’s inspect tool to get a feel for different pages. Hover over each field to see exactly where the data is stored. Sometimes the data you want might not be in a table but in a div tag, or you might want to grab text from a body tag. It’s best to familiarize yourself with how different pages are set up to move forward.

We’ve now effectively used the inspect tool to go through the source code and identify where the data is stored. Let’s write some code!

Step 2 - Write Some Code to Scrape the Web Page

So, let’s get set up. The first thing we want to do is send a request to the page and pull the HTML source code.

2.1 - Scrape the Page and Obtain the HTML Source Code

Python has a great library for handling HTTP requests and its called…requests. The first step is pretty simple, all we want is to make a connection to the web page, and save the response so we can parse through it. So install the requests library if you don’t already have it in your environment through either:

Then copy the following code below.

We’re testing now to see if we can get a response from the web page. If all is well, you should get an output of

<Response [200]>

Note if you’re getting a response of [403], head down to the bottom of this guide where I cover some tricks to get past that.

This is a successful response and means we can carry on with our scrape. If you’re getting something else, refer to this doc that details the meaning of response codes.

The next step we want to take is extracting just the HTML in a format that we can parse. This is where we will use the super easy to use BeautifulSoup library. As we did with requests, if you do not already have the library, you can install it either through pip or conda install via the following commands:

Now import and extract the HTML from the response as follows

We now have our soup from which we can take the next step to scrape the page.

2.2 - Find the Tables

With the HTML in hand, we now need to find the tables, or wherever the data is stored. We’ve already spent the time inspecting the web page so recalling our 3 pieces of information that we got, we can find the right tables and the data that lies within.

It’s interesting to note here that when we run the code above, the number of columns in the table seems to be 3 while as when we inspect the table on the web page, there seem to be 5 headers. We can confirm this by running the code below:

The output we get should be the following.

['Year', 'Actor', 'Role(s)', 'Film', 'Ref.']

The discrepancy is due to the fact that the Year column is actually a series of merged rows for the different years. This is an example of how scraping can be tricky for different web pages. Luckily, for this page, we can navigate around that with a few little hacks.

2.2 - Scrape the Data into a Data Frame

We’ve located the table, so now all that’s left is getting the data into a format we can parse through however we want for our project.

Almost there now! All that’s left is to create a dictionary and assign our lists to their respective columns.

Our data is now in a format we can use!

2.3 - Clean the Data, Output to a File

Web pages change over time, so the last step I like to take is clean the file a little and save it to a csv file with a timestamp so I know how recent the data is and I can use this snapshot of the data in an analysis.

Voila! We’ve effectively scraped a web page. Hopefully, with these steps you should have no issues figuring out how to pull data from any Wikipedia page.

Like I mentioned before, the difficulty of a scrape can be tricky from web page to web page. The more you do it, the more you’ll start to spot the patterns, and the easier it’ll become. I would recommend you to keep practicing. If you want to see an example of a scrape of 2 other web pages, head on over to this notebook where I go through the same steps, but a little differently, for Rotten Tomatoes and Metacritic.

Tips for More Advanced Scraping

Scraping isn’t always straightforward. However, there are some patterns and events that occur every now and again that you can prepare for. Here are a few tips for some of the most common solutions I’ve needed to implement.

Web Page Won't Allow Access

Some websites, like Metacritic, only allow browsers to make HTTP requests. Essentially all your browser is doing making the code readable for human eyes. So sometimes, you may come across an issue where you get a response of [403] meaning you have made a forbidden request. Often this means that the server recognizes that it’s not a browser but a code that is trying to access the page. The trick is to add a header to your request to trick the server into thinking that a browser is accessing the page. This is a helpful page to see what a request from any browser on any operating system looks like

Pull From Multiple Pages

Often, the data you’re interested in might not all be on the same page. Sometimes you might want to pull 70 pages with 100 rows each of data. You don’t want to be doing this manually setting the URL every time that’s for sure. Luckily, it’s easy to write a loop to adjust the URL and pull from pages sequentially and append the data to our lists.

Let’s say we were to take the Metacritic example above. What if I wanted to scrape the review data for every game ever? that seems like a lot, but once you’ve figured out how to do one page, it’s really quite simple.

Look at the URL. In this case, we can see that at the end of the URL the page number is set to 0. Therefore, to access any of the other pages, all we have to do is change the page number. We can do that in a loop as shown below

Now all we need to do is put it all together. Take what you’ve written for your scrape and put it inside the loop. Note that this might take a little while, so do it in small chunks while debugging. Once you’re happy with the result, set your loop to the max number of pages and let it rip!

Where to go From Here?

Hopefully, this guide has helped you on your journey to answer some questions you may have about the world. There are a ton of other ways to scrape the web, and it becomes much easier if the developers of the site you’re looking to access have built an API for you to access. But the same ideas will still apply, and as long as you’re comfortable with understanding the structure of a site, you’ll be fine. Just practice, practice, practice and you’ll get the hang of it. If you have any questions, always feel free to reach out! And if you put together a project, let me know! I’d love to check it out and hear your thoughts.
What Happens After You Win an Oscar? /  by Usamah Khan

Supposedly Richard Feynman once said “the Nobel Prize will be the tombstone on all great work”. Ironically he went on to win the prize for groundbreaking work, but at the core he raised a valid question which I think is ‘what happens when after years of passionate work and putting in your all, you finally receive recognition at the highest level’?

Most disciplines have an award at the top. One that’s highly coveted, more prestigious than all the others and reserved for experts, the best of the best - The Nobel Prize, Fields Medal, Pulitzer Prize and so on. Becoming an expert requires a commitment of mind, body and time while navigating the many inevitable obstacles that get in the way of achieving success. More often than not it’s only those with passion and a fire inside who can surmount the largest of obstacles to produce truly groundbreaking work. But what happens when people achieve success and recognition for their work? Rarely do those who practice in a field and win an award do so more than once.

Is this because people genuinely only have enough in them to produce one piece of groundbreaking work in their lifetime? Or is it because that once they receive this recognition, they no longer have the drive or passion to produce and overcome obstacles like they used to?

This last question got me thinking about how I could find a data-driven answer. But when talking about passion and creativity, we’re talking about variables that on their own don’t have any direct measures aside from rewards. There’s no ‘passion scale’ or ‘creativity spectrum’, just acknowledgment when work is extraordinary. So then how can we measure passion before and after recognition? This got me to thinking about cinema and a certain actor.

The McConnaissance

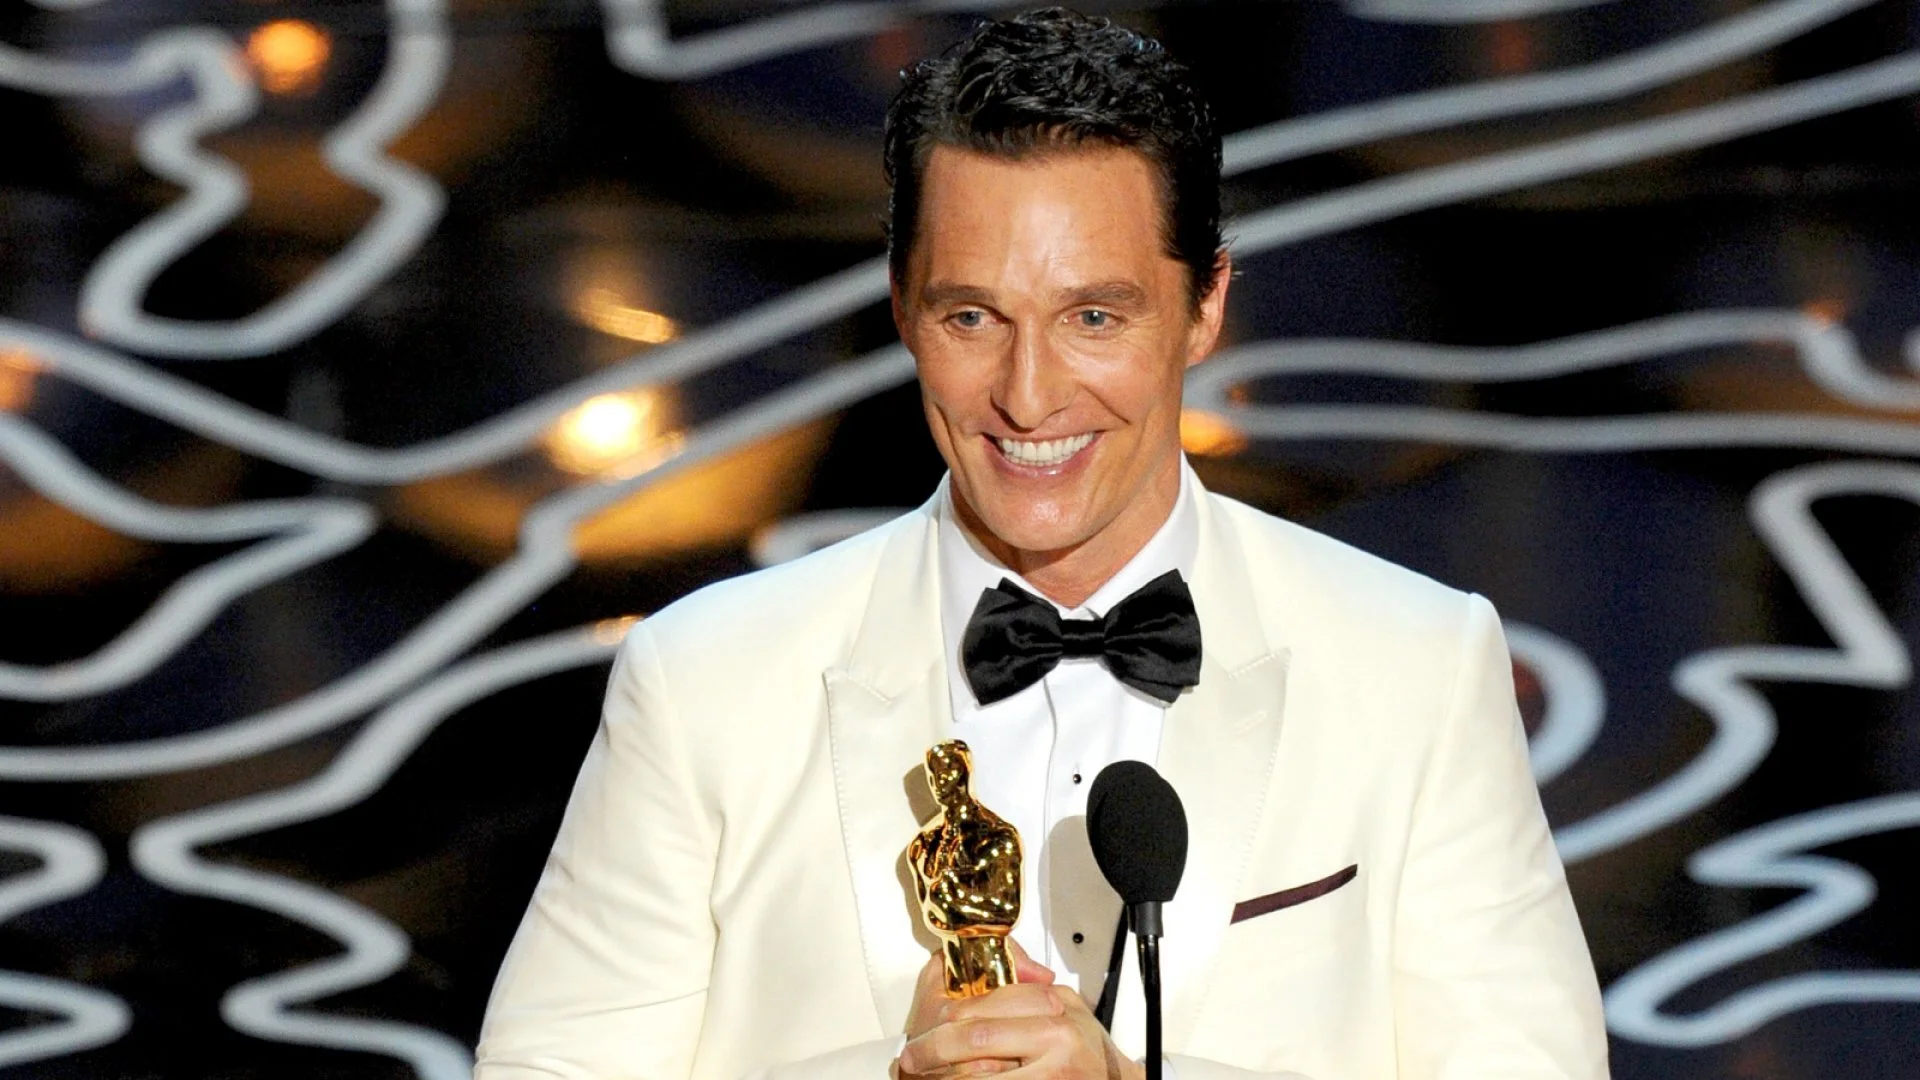
The smile of an Oscar winner

The smile of an Oscar winner

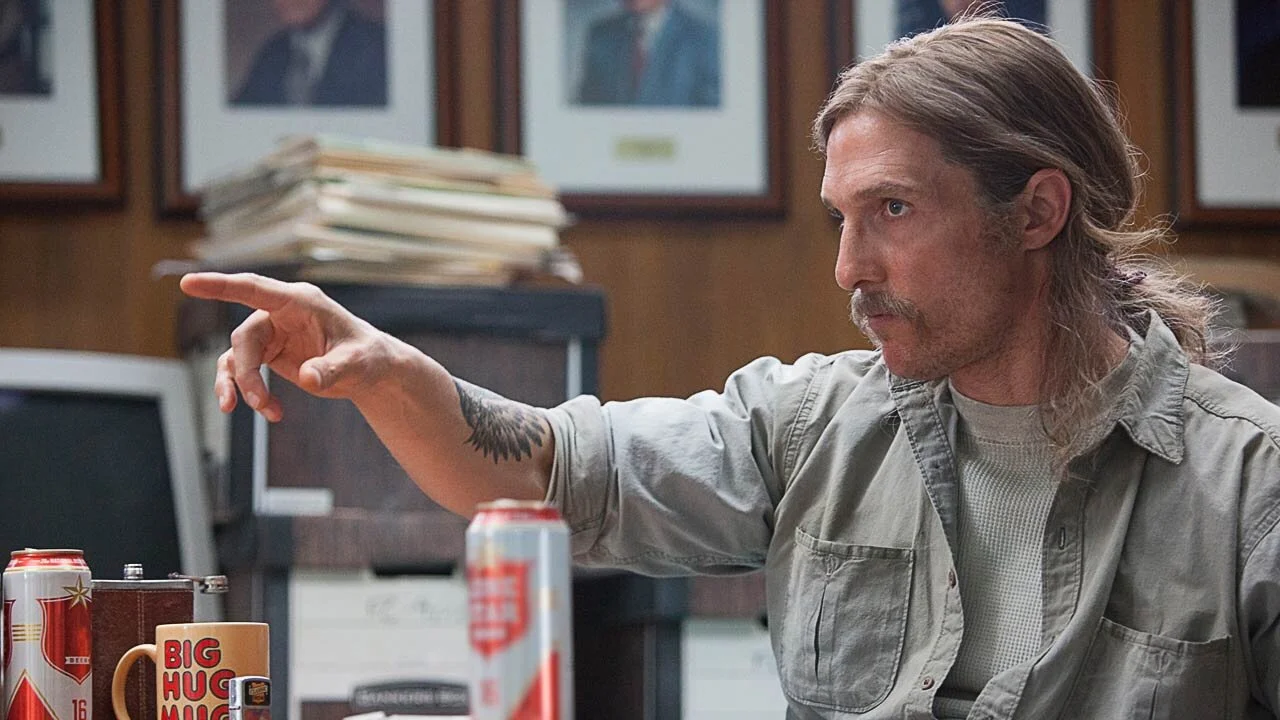
Remember Matthew McConaughey? Between 2011 and 2014 he was experiencing a revival of his career, taking on more nuanced and cerebral roles than the usual handsome, romantic heartthrob characters he was known for. He performed in a slew of critically acclaimed and high grossing films such as “Mud”, “The Lincoln Lawyer”, “Bernie”, “Interstellar”, and a stint on television in one of my favourite shows - “True Detective”. Many critics referred this time as the “McConaissance”. He truly worked on revitalizing his career and this time eventually culminated in him receiving an Academy Award for Best Actor for his portrayal of Ron Woodroof in “Dallas Buyers Club”. 

Matthew McConaughey as Rust Cohle in True Detective

Matthew McConaughey as Rust Cohle in True Detective

However, since then, his career has been quiet with only a handful of lackluster appearances in films such as “The Dark Tower”, “Beach bum” “The Gentleman”. In almost the same amount of time that the “McConaissance” was declared, it ended. So to our question, did Matthew McConaughey lose whatever it was that drove him to portray roles to critical acclaim? Is this a correct observation to make? And is this a common occurrence among other actors after they achieve the highest award in acting?

The Academy Award for Best Actor

Let’s first look at how we can come up with a measure for creativity and passion. The Academy Award, more commonly known as the Oscar, for Best Actor/Actress, is given out once a year and is probably the most highly coveted award in the field of cinema. It is given “in honor of an actor who has delivered an outstanding performance in a leading role while working within the film industry”. Only a handful of artists have won the award more than once. In fact in its 92 years of running, 83 men have won “Best Actor”, and 76 women have taken home the title of “Best Actress”. 

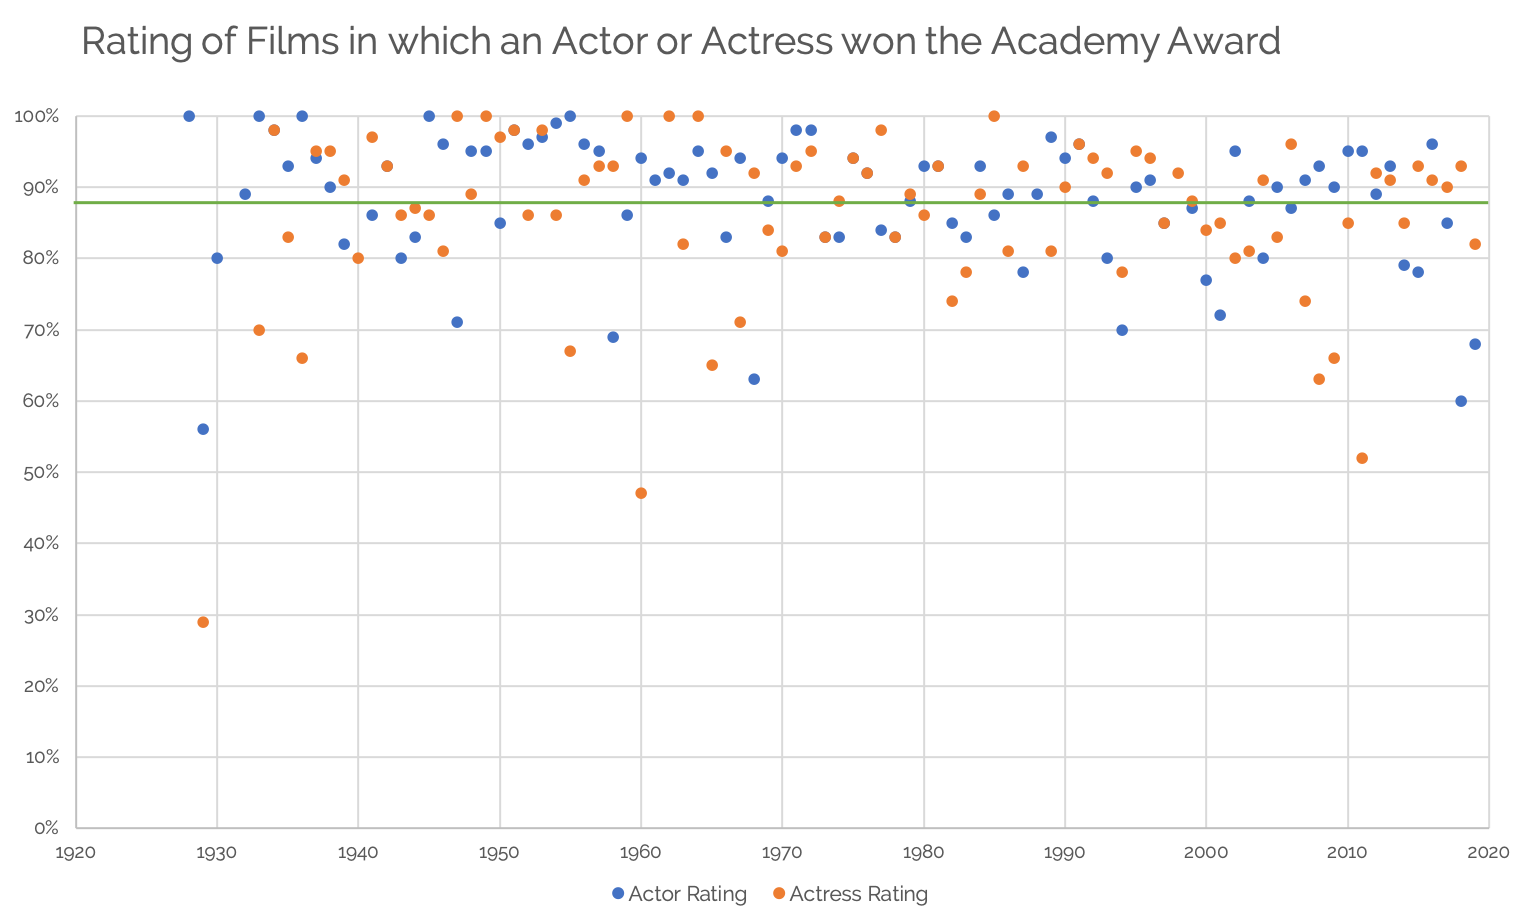
In addition to this, an outstanding performance is more often than not in a critically acclaimed film. In fact the average ratings for films in which there was a winner for best actor/actress on review aggregator Rotten Tomatoes is 88% / 86% respectively.

Figure 1 - Chart showing the rating of films in which the lead actor or actress won an Academy Award for their performance. Compiled from scraping Rotten Tomatoes for ratings and Wikipedia for academy award winners.

Figure 1 - Chart showing the rating of films in which the lead actor or actress won an Academy Award for their performance. Compiled from scraping Rotten Tomatoes for ratings and Wikipedia for academy award winners.

With that, maybe we can look at the ‘quality’ of films via proxy variable - in this case, ratings - before and after an actor or actress won the Academy Award, as a measure of the quality of their career. We can use the scores from Rotten Tomatoes - a site that may be familiar to you, but briefly - they are an aggregator that take all reviews in all forms and scales and simply take whether or not the review was positive or “fresh” (thumbs up, above 60% or 3 stars) and give a score that “represents the percentage of professional critic reviews that are positive for a given film”. I added a section in the methodology if you’re keen on understanding further.

Measuring The McConnaisance

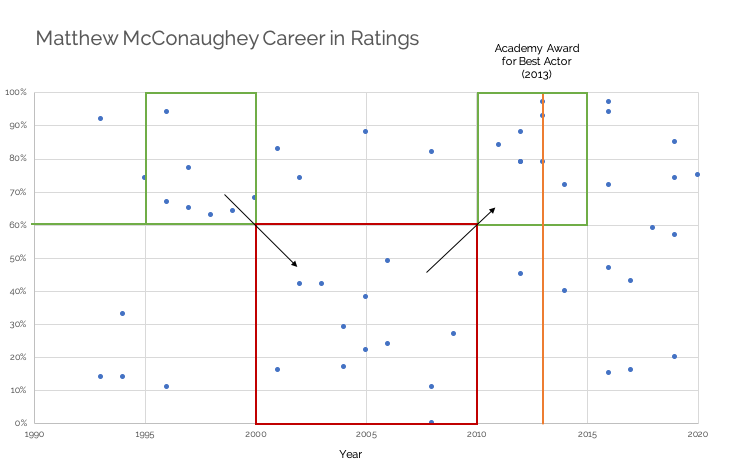
We started our discussion looking at Matthew McConaughey so now let’s look back at the question in his context. The figure below shows his career from 1990 to 2020 and the ratings the films he acted in received. In the late 90s he seemed to be performing in some highly rated films. Yet something changed between 2000 and 2010 where the opposite was true. 

Figure 2 - Chart showing ratings over the course of Matthew McConaughey’s Career

Figure 2 - Chart showing ratings over the course of Matthew McConaughey’s Career

During “The McConnaisance”, between 2010 and 2015, he was experiencing a definite height of his career that seemed to culminate in his 2013 Oscar. But what’s interesting to note is between 2015 and 2020 McConaughey acted in a greater number of films than any 5 year period before. In addition, there seems to be a larger spread in the quality of these films.

Is the variance in this quality a result of his acting? Perhaps his critical accomplishments net him enough demand that he could afford to act in films that may offer a higher return in box office success, but not in ‘quality’ of role. Regardless he’s kept busy so his drive to continue acting has not wavered.

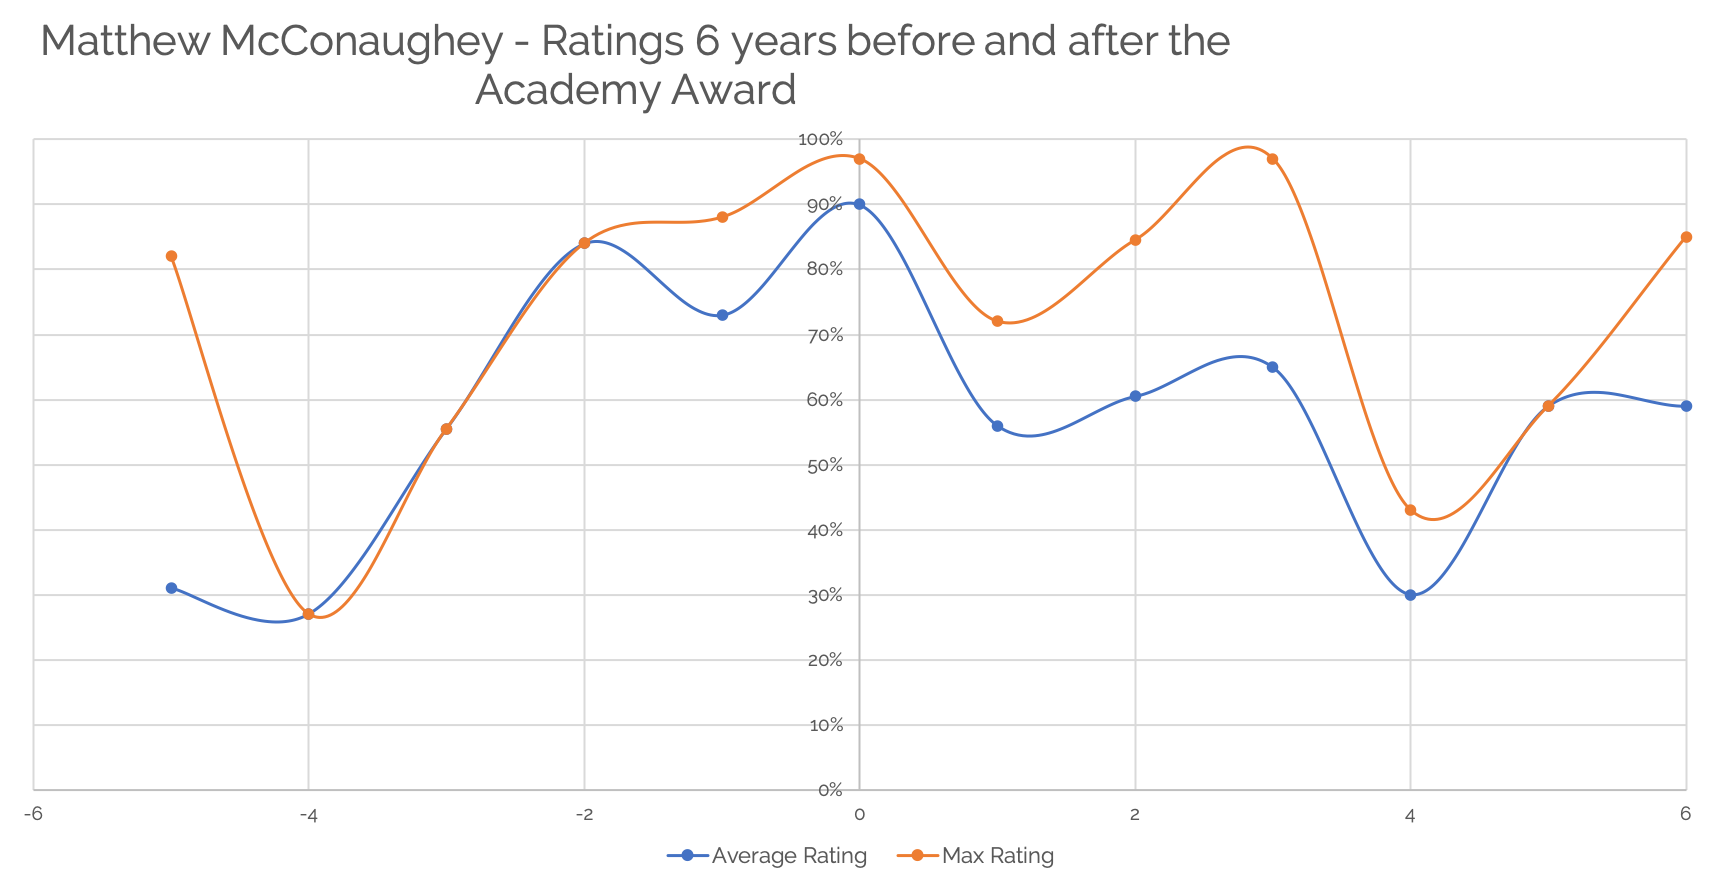
Whatever the answer, there was a definite change in his behaviour over the 6 years after his Oscar win from the 6 years prior to it. We can explore this further by looking at the average ratings of the films he was in over this 12 year period and also extract his highest rated film of each year. 

Figure 3 - Chart showing ratings over 6 years before and after winning the Academy Award for best Actor

Figure 3 - Chart showing ratings over 6 years before and after winning the Academy Award for best Actor

Taking time = 0 as the year he won the Academy Award, it’s evident that there was a gradual incline in the quality of the films he performed in. In fact, the average ratings largely seem to follow the same trends from about 4 years until his award. At this point however, there started to show a difference between the two metrics. We can gather from this that while Matthew McConaughey’s career since has included some very well received films, there've been quite a few movies of a lesser quality bringing down his yearly average rating.

Is this a common occurrence?

So in the case of Matthew McConaughey, we have two sets of information indicating some sort of behaviour change. But what about other actors? Did their pre/post success follow the same pattern? We can compare them along the same lines as we did with McConaughey, standardizing the year they won the academy award as year 0 and looking at 6 years before and after. 

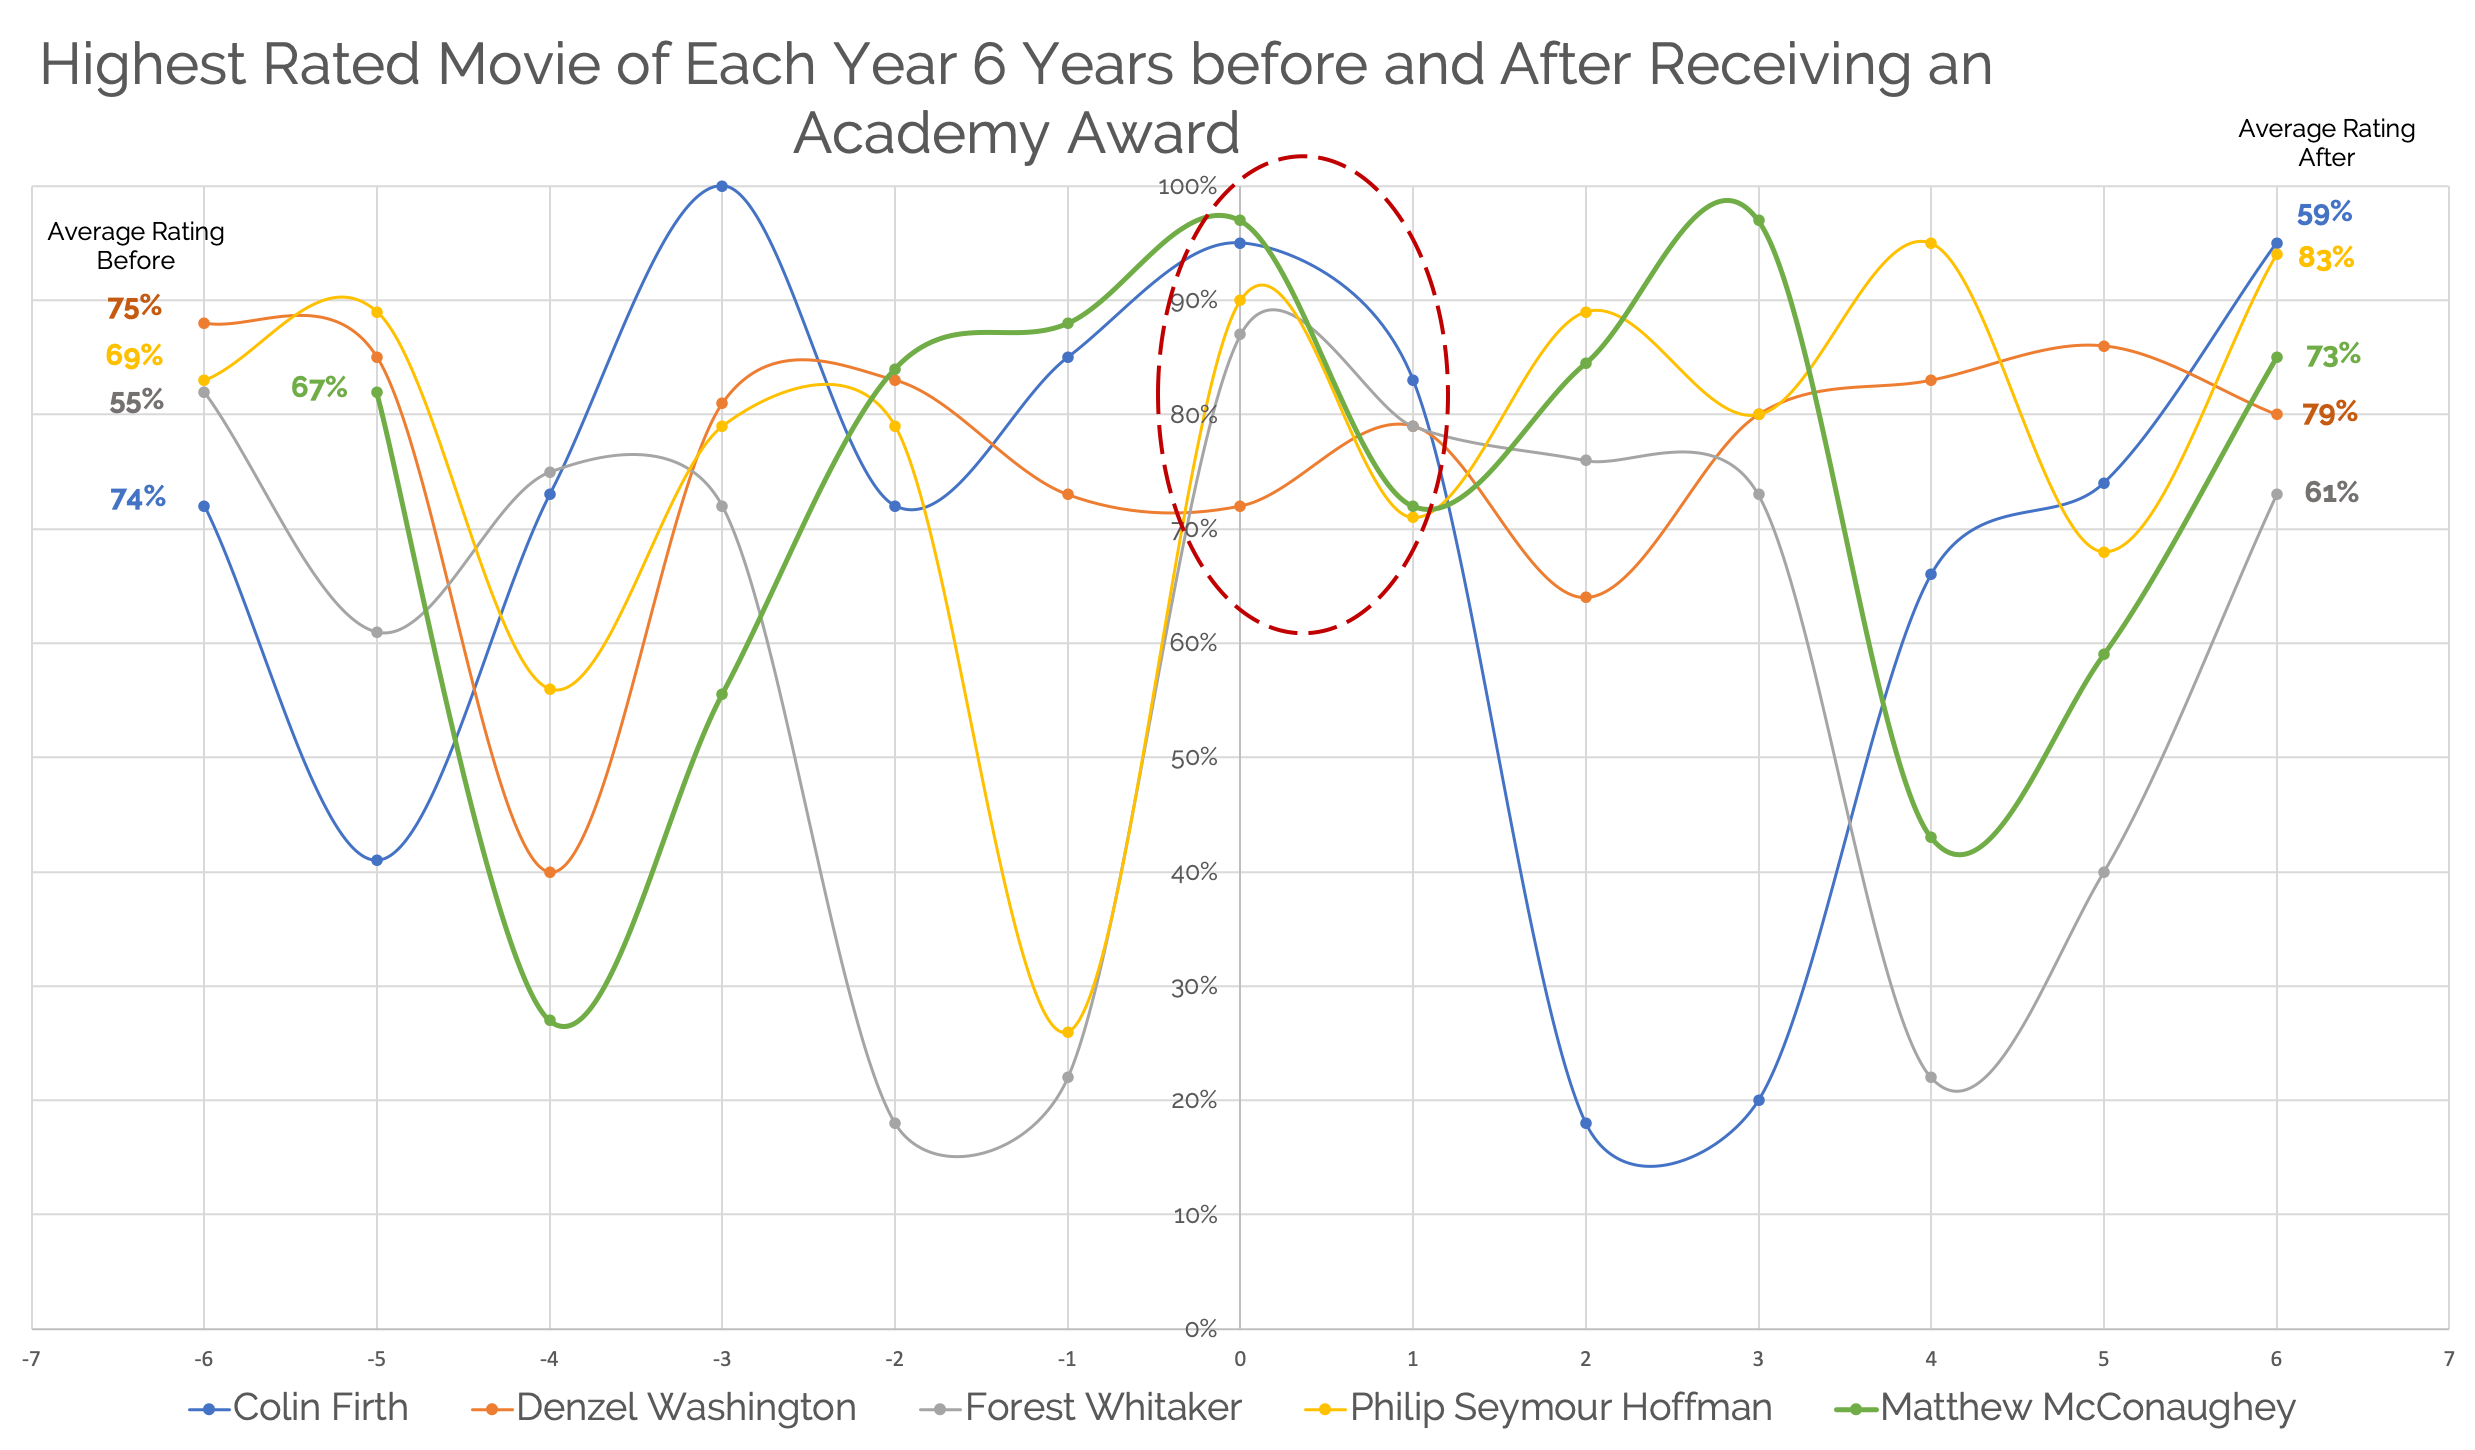
Between the years of 2000 and 2014 there were only a few actors who won the academy award who had careers prolific enough to have data for 6 years before and after. We’re going to take a closer look at 4 of them alongside Matthew McConaughey.

At first glance there doesn’t seem to be as visible a pattern before and after. However, looking closer, it becomes interesting to note that at time = 0 (the year of winning the award) actors in general are experiencing a peak in their careers, and more interestingly, in general seem to be observing a short term decline in their ‘best performance’ of the year. Looking at the longer term trends they somewhat stabilize but what’s fascinating is what seems like a ‘hangover’ to their win.

Figure 4 - Chart showing ratings over 6 years before and after winning the Academy Award for best Actor for a sample set of actors

Figure 4 - Chart showing ratings over 6 years before and after winning the Academy Award for best Actor for a sample set of actors

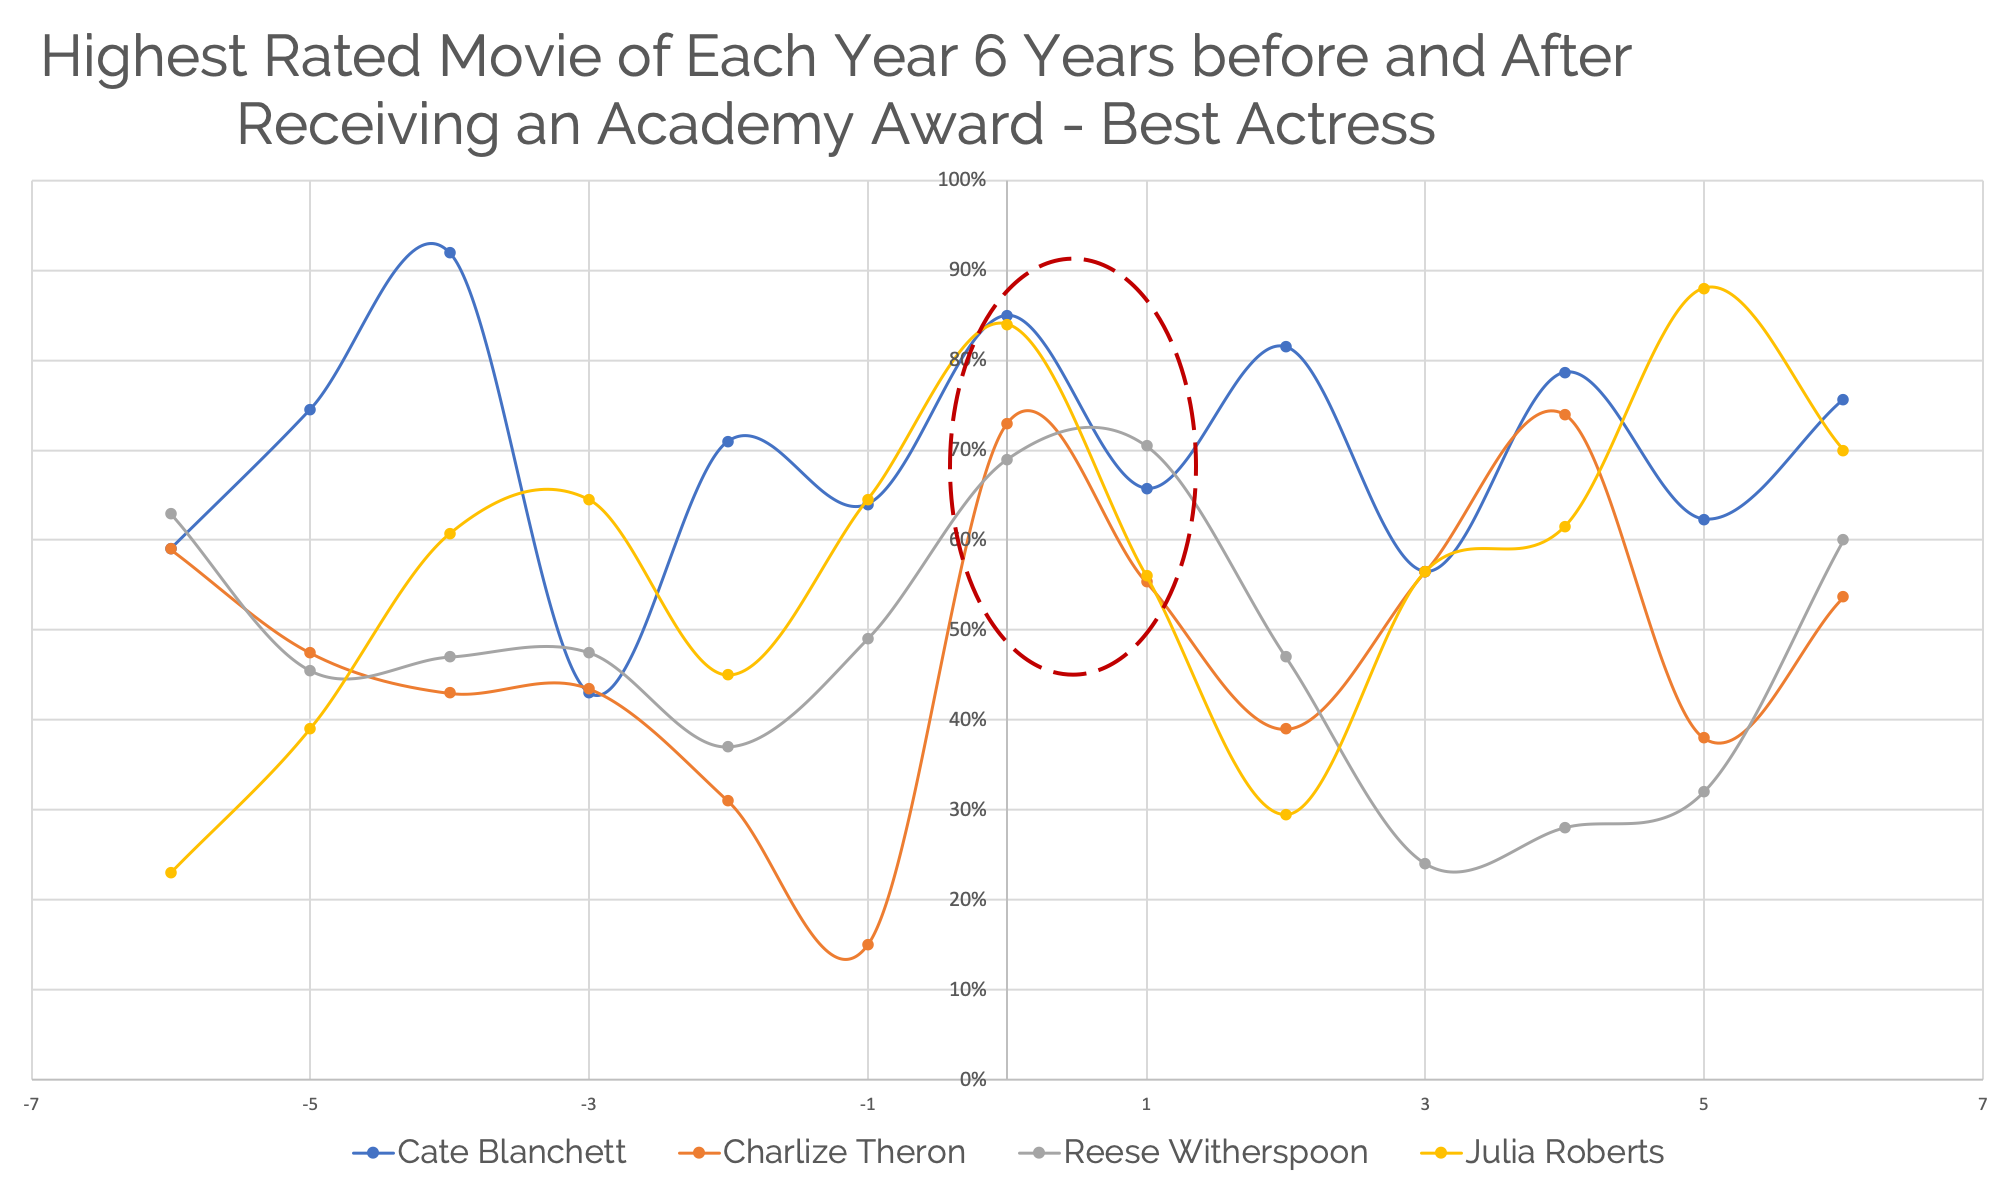
Can we now say with any certainty that an Academy Award win leads to a dip in performance? It certainly seems that something happens, with some actors being able to bounce back quicker than others. Taking a sample set from best actress winners in the same vein as actors, we can see a similar pattern with a decline in performance in the short term.

Figure 5 - Chart showing ratings over 6 years before and after winning the Academy Award for best Actress

Figure 5 - Chart showing ratings over 6 years before and after winning the Academy Award for best Actress

Where do we take this?

The study illuminated some insightful patterns among academy award winners. But what do we take from this? Do we stop giving out awards to encourage creative work? That seems a little far fetched, especially considering that perhaps it’s in pursuit of this recognition that creatives find their drive. I find this is reflected more and more in today's society. We concern ourselves so much with likes, views, comments and followers that a lot of drive to create content is fuelled by these metrics. 

This ultimately raises an observation that in acting, there is no objective indicator of performance - or at least not one that I’m aware of. The difficulty lies in determining a quantitative measure that does not currently exist. With that in mind, it would be worthwhile to develop a more complete measure of an actor’s performance within a given year. Maybe this framework or model could include additional measures such as the actor’s time on-screen, the number of roles they acted in within a given year,  the box-office earnings from their movies, the pay they received, along with the overall critic rating for the film itself. This metric could perhaps then be extrapolated as an actor’s score - deepening and complexifying the rating system that we are taking from Rotten Tomatoes, to better quantify creativity. Perhaps we can even offer a data-driven approach to acting that artists, dancers and even amateur actors on Social Media platforms such as Instagram and TikTok have been following for years.

We can also look at other fields. For example, athletes don’t seem to follow the same success patterns as actors or Nobel Prize winners. Fairly often, star athletes tend to reign over many years and amalgamate multiple wins while at the top of their game across all forms of sports. 

Micheal Jordan played 15 NBA seasons, out of which he won 6 NBA championships with the Chicago Bulls and to this day Jordan is the all-time 2nd highest scorer of the NBA. Jordan’s reign and success, however, was objectively measured and easily quantifiable. One could argue that his achievement of the highest levels of recognition in the sport, was a direct outcome of effort and quality of his work. This correlation between quality of work and recognition seems much more linear than the Academy Awards rubric for “winning” the Oscar which is neither objective nor static over time. And this is basketball, where it could be argued that the highest level of success in the sport - winning an NBA championship, could still be attributed to the larger team, rather than simply one individual.  

When we turn to look at other more individualistic sports than basketball such as Olympic sprinting or Tennis, there emerges perhaps an even stronger correlation between quality of work and recognition/success.

Ultimately, actors provide us a great source of entertainment. One could argue that during this time, locked indoors and unable to go outside, we’ve turned to them. They help get us through the evenings and keep us company giving us an outlet to feel our emotions or escape from them. So they should be rewarded. But the more so applauded for work they create in such a risky field with no guarantees and no safety nets. Maybe we can learn to do this as well. With that, I’ll end with a thought from the great Rodney Mullen.

“Just find joy in what you do for the sake of it. And then recognize how you're being shaped in the process, and hopefully, over time, you become a better person through it.” 

Methodology

There were a couple of ways I went about structuring my thoughts and gathering the data. Below I go over some of my thought process and what I did, but feel free to reach out if you have any questions!

Exploring the Questions

The first step I needed to take was to identify a measure for ‘quality’. Cinema is a subjective field. A film may be lauded by some but criticized by others, and outside of awards, there aren’t really any metrics to measure individual performance as such.

However, there are metrics that one can attach to the quality of a film, such as ratings and box office performance. But these metrics are difficult to standardize. Take in the case of movie critic reviews. All over the world, critics and journalists (professional or amateur) go to screenings, absorb the film and share their thoughts sometimes attaching a score that could be anything from a 1-10 scale, 5 star rating or simply give a thumbs up/thumbs down. Furthermore between all of these systems, it’s difficult to make sense of the subjective nature of scoring. Legendary film critic Roger Ebert once reflected on how his style of rating movies changed over time according to what his readership was looking for. He found they weren’t looking for a ‘review’ of the film, but simply advice on whether or not they should spend their evening watching the film in question.

There are a few ways to solve this problem, but as I briefly touched on, review aggregator Rotten Tomatoes seems to have done it best. Simply, as you may be familiar with this, they take all reviews in all their forms and aggregate whether or not the review was positive or “fresh” (thumbs up, above 60% or 3 stars) and give a score that “represents the percentage of professional critic reviews that are positive for a given film”. As this system allows for reviews from all sorts of systems to be aggregated, Rotten Tomatoes is often one of the more trusted or go-to indicators of public opinion.

Getting the Data

To attempt to answer the questions above, I was going to need data - a lot of it…but also not all of it. To do this and help draw out some of the relevant overarching data, I made a few assumptions. Firstly, the focus was on ‘modern’ cinema, starting from 2000 to 2014. Movie rating systems evolved around this time and due to the growth of the internet, this is when the quantity of reviews available grew and aggregators such as Rotten Tomatoes seem to give a better indication of critical acclaim. Kind of like how it’s easier to trust a restaurant rated 4.2 with 1000 reviews than one rated 5 with 8 reviews.

Secondly, the driver for this was based on a long and winding thought process that started with Matthew McConaughey. So I based the timeframe on a pattern of performance pre and post his Academy Award in 2013 to now. As such, I want to look at patterns within the same time frame of +/- 6 years from an actor’s first academy award win.

The data was collected from two sources. I wrote a Python script to0 scrape Wikipedia to get a list for all Best Actor and Actress. With that, I used the data and to guide a further web scrape of each winner's filmography page on Rotten Tomatoes. I’m happy to share my code, just drop me a line!